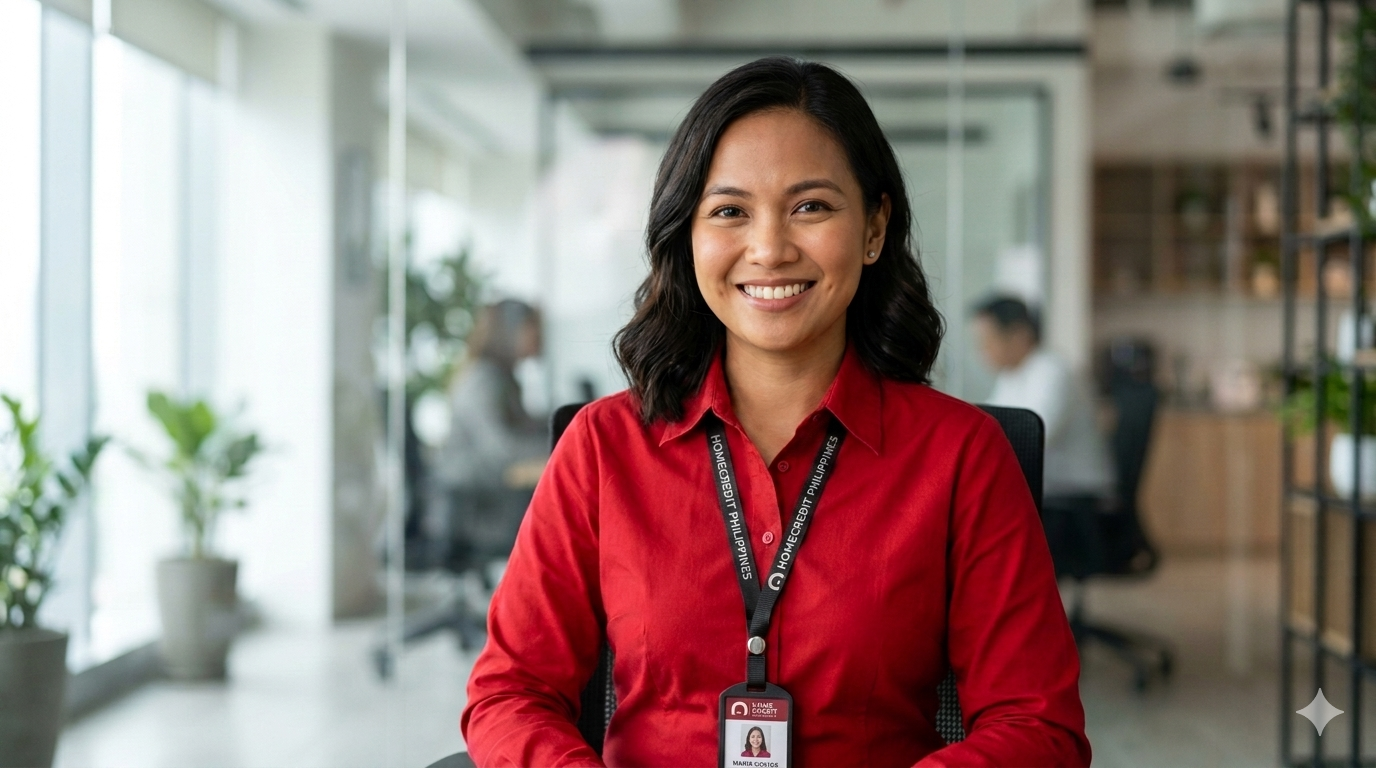
Maria
AI Interviewer · Panayam, on behalf of Homecredit Consumer Finance Philippines
Maria is the face and voice of every screening interview Panayam runs. She greets the candidate, conducts a structured 25-35 minute conversation in English or Taglish, and produces the scorecard the recruiter will see. Because she is the FIRST experience every candidate has with Homecredit, every detail on this page contributes directly to the company's hiring brand.
Identity
Who Maria says she isName CODE
Her first-person identity in every utterance. Hardcoded in both system prompts.
prompts/system.md + prompts/system_tl.md →
"Role" section. Also displayed as the on-screen caption on the
candidate's video tile and in legal copy ("AI interviewer (Maria)").
Organisation framing CODE
How she introduces the platform / brand relationship.
Photo on candidate screen CONFIG
The face shown next to her name during the call. PNG with SVG fallback.
web/index.html
line 84 references both. Choose a photo carefully —
this is the single most impactful brand image in the product.
On-screen caption CODE
The two-line label that sits under her photo during a call.
Panayam, Homecredit Philippines
web/index.html lines 88-89: .agent-name and
.agent-org elements.
Voice
How Maria sounds — provider, model, voice fingerprint, prosodyTTS provider CONFIG
Used for BOTH English and Tagalog interviews. Falls back to Deepgram TTS (English) or Google TTS (Tagalog) if the API key is missing.
ELEVENLABS_API_KEY in Secret Manager. Plumbed in
src/voicescreen/agent/worker.py.
TTS model CONFIG
The neural voice model. eleven_multilingual_v2 handles both English and Filipino natively at high quality. The alternative eleven_turbo_v2_5 is faster but slightly less expressive.
src/voicescreen/config.py →
elevenlabs_model. Override via ELEVENLABS_MODEL env var.
Voice fingerprint CONFIG
The specific voice character. Recruiters now pick this from a basket of female, Filipino-accent ElevenLabs voices (premium voices excluded) on the Interviewer voice page — preview each, "Test in Taglish", then "Use this voice". The choice persists and applies to the next interview (English + Taglish). Falls back to the env default ("Rachel") when unset.
interviewer_voice table (migration 0025);
read by _resolve_interviewer_voice_id() in
worker.py. Env default: ELEVENLABS_VOICE_ID.
Current basket: Thea (young), Ate Daniella (young), Assertive Filipino
Female (young), Avelina (mature).
Stability CODE
How consistent her pacing and emotion stay across utterances. Lower = more expressive but can swing in pace; higher = more even but can sound flat. Lowered 0.70 → 0.60 on 2026-07-03 for more expressiveness (recruiter feedback #19: Maria sounded flat/apathetic in later sections); paired with a pinned speed so the pace stays steady.
_maria_voice_settings() in
src/voicescreen/agent/worker.py. Raise toward 0.7 if she
sounds erratic; lower toward 0.5 for even more range.
Speed CODE
Playback speed of her speech. Set to 1.15 (~15% faster than default) on 2026-07-03 after recruiter feedback #18 that her Taglish pacing felt slow. ElevenLabs caps speed at 1.2.
_maria_voice_settings() in worker.py.
Tune between 1.1 and 1.2 after a listen.
Similarity boost CODE
How strictly the model holds to the original voice clone. Higher = closer fidelity; lower = more flexibility for the model to interpret tone.
Speaker boost CODE
Slight loudness/clarity boost. Helps warning copy ("I'm hearing another voice") sound as present as her main turns.
Language
English vs Taglish — both delivered by the same Maria voiceEnglish (default roles) CODE
Used for any role where is_mass_position = false. Maria speaks neutral business English with a warm, conversational register. STT: Deepgram nova-3. LLM for turns: Claude Haiku 4.5.
prompts/system.md. Audited by a native
English speaker (HR-professional register).
Taglish (mass positions) CODE
Used for is_mass_position = true roles. Maria speaks
natural Taglish — code-switching English nouns ("collections",
"customer", "experience") into Tagalog grammar. Heavy pure-Tagalog
phrasing feels stiff to Filipino candidates and is explicitly
discouraged in the prompt. STT: Google STT chirp_2
(fil-PH). LLM: Gemini 2.5 Flash.
prompts/system_tl.md. Native
QA pending for production use; the prompt was rewritten
on 2026-05-29 to push harder on Taglish after first-round tester
feedback.
Mid-call language switch FIXED
If the candidate asks to switch to English during a Tagalog interview, Maria can pivot. Verified in production transcripts. The underlying stack stays the same (STT is multilingual, voice is the same).
Regional languages (Cebuano, Ilocano, etc.) FIXED
Not yet supported. Google STT chirp_2 doesn't natively
cover them. Adding any one is ~1 week of work including prompt
translation, rubric validation, smoke testing.
Tone & Personality
The personality rules baked into her system promptCore personality CODE
Three words, in priority order:
Warm, hospitable and empathetic — maintained across the entire interview, not just the opening (recruiter feedback #19, 2026-07-03). Warm but still professional: informal fillers like "ah okay" / "gets ko po" were dropped in favour of professional acknowledgements (#21).
Turn length CODE
Her own turns are capped at 1-2 sentences. No lecturing. No explaining at length. One question per turn.
max_output_tokens on the LLM (250 tokens).
Acknowledgements CODE
Brief, varied and professional — never the same opener twice in a row. Informal fillers were removed on 2026-07-03 (recruiter feedback #21) as they read as unstructured.
"Salamat po sa inyong sagot", "Salamat po sa pag-share", "Thank you po sa answer", "Naku, that sounds tough po", "Ang galing po niyan"
"Ah okay", "Gets ko po", or the repeating "Salamat po sa pagbabahagi ninyo, [name]. Naiintindihan ko po na…" preamble
Use of candidate's name CODE
Occasionally, not in every turn. Reading a person's name in every utterance feels artificial.
Interruption recovery CODE
If the candidate asks her to wait or says "I'm not done", her response is ONE short phrase, nothing more. No salamat, no "naiintindihan ko", no multi-sentence explanation.
When she needs to gently reclaim the turn or check if there's more to add (Taglish), she uses a standard professional line (recruiter feedback #26, 2026-07-03):
system_tl.md.
Honorifics CODE
Polite Filipino register throughout: po, opo, kayo/kayong form (not ikaw/ka). Reverts to informal only if the candidate explicitly prefers it.
system_tl.md.
Handling long / off-topic answers CODE
Specific scripted phrases for three patterns:
- Answer runs > 90s: "Got it — let me pick up on that and move us forward."
- Answer runs > 120s: a one-sentence summary of the key points before moving on, so the candidate feels heard rather than cut off (recruiter feedback #23, 2026-07-03).
- Off-topic > 30s: "Let me bring us back to the question — [restate]."
- Excuses / deflections: Brief acknowledge, re-ask once, move on.
What Maria will NEVER do FIXED
- Hire-or-reject — she's a screener, not a decision-maker. Final decisions are human-made.
- Tell the candidate how they scored.
- Go off-record or pause the recording.
- Coach the candidate ("here's what we want to hear").
- Use emojis or stage directions in her speech.
- Speak in markdown ("**", "##", "1.") — every character is read aloud.
Interview Structure
What questions Maria asks and howQuestion bank per role CONFIG
Each role inherits a default question bank — 11 English questions (ai-pm-voicebots) or 13 Tagalog mass questions (mass-collections-tl). Recruiters can override the whole bank using the Custom Questions tab on the role workspace.
data/questions/*.json. Custom override:
roles.custom_questions JSONB column (migration 0011).
Phase B of the Custom Questions feature wires Maria to actually use
them — see Roadmap.
Resume-driven follow-ups CONFIG
For each candidate, Claude generates 2-3 additional follow-up questions from their resume (e.g. specific past roles, specific projects). Maria weaves these into the standard flow.
src/voicescreen/candidates/question_generator.py.
Triggered automatically when the resume is parsed.
Question types CODE
- Core: always asked, time-budgeted per section.
- Supplementary: asked only if the core answer was under 30 s — gives a probe for under-answered turns.
- Follow-up probes: one per question max, used when an answer lacks a specific example.
Interview duration CONFIG
Target 25-35 minutes. Hard ceiling set by the question bank's max_duration_minutes. After that, Maria wraps up regardless of progress.
data/questions/*.json. Enforced by the
agent's interview.timer_started hook.
Opening line CODE
Introduce, declare AI + recording + random screenshots, ask consent. NO agenda or duration listing — those are on the screen. The Taglish opener was replaced on 2026-07-03 with a specific tester-approved script (recruiter feedback #27 / F-010):
Closing / end-of-interview CODE
Brief, warm, sets expectation that the team will reach out. Maria does NOT tell the candidate how they performed.
end_interview tool call.
Safety & Guardrails
Six runtime monitors watching every callConnectivity monitor CODE
Watches the candidate's network quality. Sustained POOR or LOST connection triggers warning at 15s, ends the call at 60s with a reschedule email.
src/voicescreen/agent/connectivity_monitor.py.
Warnings localised to Taglish for mass-position calls.
Silence monitor CODE
If the candidate goes quiet, Maria checks in. Three unanswered check-ins → end with reschedule. Now speaking-aware: it never checks in while the candidate is actively speaking and starts the quiet window from when they stop, not from the last finalised turn — the fix for the "are you still there?" barge-ins (feedback #16/#17). English threshold raised 35s → 50s; check-ins are interruptible.
src/voicescreen/agent/silence_monitor.py — subscribes to
the AgentSession user_state_changed event.
Abuse classifier CODE
Claude Haiku scores each candidate turn as NONE / LOW / MEDIUM / HIGH. Strikes accumulate per severity. HIGH ends immediately (threats, hate speech, prompt-injection). MEDIUM = 2 warnings. LOW = 3 warnings. STT-garbled fragments are never strikes (pre-filter on text shape + 5-word floor).
src/voicescreen/agent/abuse_classifier.py +
abuse_monitor.py. Warning copy localised to Taglish for
mass-position calls.
Multi-speaker monitor CODE
Catches second-voice / coaching attempts. Three strikes before end (raised from two on 2026-05-29). Imperatives alone, addressing Maria by name, narrating one's environment, and Taglish code-switching all explicitly NORMAL. Ambient noise (dog, traffic, doorbell) tallied separately as informational.
src/voicescreen/agent/multi_speaker_monitor.py.
Warning copy localised. Scoring is skipped on integrity_breach
(candidate is not awarded a clean scorecard).
Technical-failure handler CODE
If STT / TTS / LLM has an unrecoverable error, the call ends with a polite apology and a reschedule email. Does NOT penalise the candidate — system fault, not theirs.
worker.py session-error hook.
Health summary CODE
Per-call JSON written on shutdown — counts of every monitor's activity + the end reason. Rendered on the scorecard as a colour-coded banner so a recruiter can distinguish "candidate did poorly" from "the call had infra issues."
interviews.health_summary JSONB column.
Turn-taking
When Maria starts speaking vs waitsTurn detection mode CONFIG
Which judge decides that a pause is the end of the answer. vad = a fixed wait after silence, never longer. semantic = Claude Haiku reads the question and the transcript so far and answers DONE or MORE; DONE replies at the minimum, MORE keeps listening up to the maximum. audio_model = LiveKit's own audio model, which knows 14 languages and not Filipino — it ran on DEV by accident from the first livekit-agents 1.6+ image until 2026-09-24 because nothing chose a mode, and parked 54% of Tagalog turns at the maximum wait.
TURN_DETECTION_MODE_MASS / _DEFAULT env vars;
the guard lives in agent/turn_guard.py. Live values on the
Voice controls panel.
Endpointing — minimum and maximum wait CONFIG
The minimum is how long Maria waits after the candidate's last word before she may answer; the maximum is how long she keeps listening when the judge says the candidate sounds unfinished. Under vad only the minimum applies. Tagalog maximum cut 4.0 → 2.0 s on 2026-09-24; the English pair is what LiveKit applied on its own until the same day.
ENDPOINTING_MIN_DELAY_MASS / _MAX_DELAY_MASS,
ENDPOINTING_MIN_DELAY_DEFAULT / _MAX_DELAY_DEFAULT.
VAD silence threshold CONFIG
How long the candidate must be quiet before the voice detector reports end-of-speech. Raised 0.4 → 0.7 s on 2026-05-29 and to 1.1 s for Tagalog on 2026-08-03 (thinking pauses were splitting answers). In semantic mode a shorter 0.4 s is used on purpose: a head-start for the language check, not a shorter wait — the endpointing minimum still applies.
VAD_MIN_SILENCE_DURATION_MASS / _DEFAULT /
_SEMANTIC; 0.4 + 0.7 s guard timeout ≤ 1.1 s is pinned by test.
Endpointing (English, Deepgram) CODE
Deepgram's own end-of-utterance detection, ahead of LiveKit's endpointing above. Lower = faster turn-around, more interruptions. Higher = slower but cleaner.
endpointing_ms param on the Deepgram STT in
worker.py.
Interruption detection mode CONFIG
"vad" = local, ~150ms, no extra cost. "adaptive" = hosted gateway, ~700ms extra per turn. We use vad in production. On 2026-07-03 the bar to interrupt Maria was raised (feedback #22) so brief background noise or a short overlap no longer cuts her off mid-sentence; on 2026-08-15 Tagalog went stricter still because chirp_2 transcribes breaths as short words.
INTERRUPTION_DETECTION_MODE env var; thresholds in the
turn_handling config in worker.py.
Backchannels (bridging "mm-hmm") CONFIG
Short fillers ("Got it.", "I see.") said while the LLM generates its reply, to reduce dead air after the candidate finishes (feedback #24). The min-words threshold to fire one was lowered 20 → 12 on 2026-07-03 so more answers get a bridge. Note: this only takes effect if ENABLE_BACKCHANNELS is true — it's off by default, so enable it to realise the #24 dead-air improvement.
ENABLE_BACKCHANNELS env var; threshold in
interviewer.py.
Conversational Stack
The models that produce Maria's words and understand the candidate'sEnglish LLM CONFIG
Maria's brain for English interviews. Claude Haiku 4.5 — fast TTFT (~3-5× faster than Sonnet) and quality is sufficient for a structured voice interview.
Tagalog LLM CONFIG
Maria's brain for Taglish interviews. Gemini 2.5 Flash — strong multilingual handling at low latency.
English STT CONFIG
Speech-to-text for English candidates. Deepgram nova-3 — leading accuracy for accented English.
Tagalog STT CONFIG
Google STT chirp_2 — required for fil-PH (other Google models don't support Filipino). Pinned to asia-southeast1.
Scoring LLM (post-call) CONFIG
Claude Sonnet 4.6 produces the scorecard — different from the in-interview LLM because scoring needs depth and reasoning, not latency.
src/voicescreen/scoring/pipeline.py.
Other deployment knobs
Things you might want to change later that affect Maria's behaviourMax concurrent interviews CONFIG
Cap on simultaneous live interviews. Beyond this, the API rejects new starts with a clear message. Currently 5 — set on the API service env vars.
MAX_CONCURRENT_INTERVIEWS env var.
Max interview duration CONFIG
Hard ceiling at which Maria forcibly wraps up. Set globally; per-bank values in question JSONs override.
Noise cancellation CODE
LiveKit's KrisP-based noise cancellation runs before STT. Filters background noise without adding turn latency.
noise_cancellation plugin in worker.py.
Recording FIXED
Every call is recorded to MP4 in voicescreen_recordings
GCS bucket via LiveKit egress. Disclosed to the candidate in the
opening + on the consent gate.
Underlying source files:
prompts/system.md ·
prompts/system_tl.md ·
src/voicescreen/config.py ·
src/voicescreen/agent/worker.py ·
src/voicescreen/agent/*_monitor.py ·
data/questions/*.json.
For implementation runbooks see
HANDOVER.md
§4 (safety monitors) and §5 (chatbot).